- Python 81.9%
- JavaScript 9.8%
- HTML 5.6%
- CSS 2.5%
- Shell 0.1%
 d7a2ce91cc Schema watcher:
- Scan coalescing is loop-agnostic: in-flight scans are concurrent.futures
futures any event loop can wait for, taken over only when their loop has
closed or stopped; each refresh() resolves only its own scans. A write on
one loop no longer hangs forever when another loop's scan is in flight.
- At most one polling task across event loops; replaced pollers exit.
- A scan or catalog write that fails transiently (internal database locked,
shared-cache lock, cancellation) re-marks the database and retries it from
later requests and sweeps, with back-off; requests are never failed by it.
Write threads mark schema changes directly (under a lock) instead of
relying on a notification reaching a loop that may have closed.
- add_database() file databases and named in-memory databases use the
default_schema_watch mode (external unless configured). Named in-memory
databases can be external: polled with PRAGMA schema_version on their
write connection. They are not scanned at registration time, which raced
plugins filling them (datasette-copy-to-memory).
- close() no longer persists a fingerprint for an owned database whose file
header shows a schema the catalog has not seen.
- The derived-table permission rule (external-content FTS) trusts the
catalog only when a stat and header read prove it is current; otherwise
it asks the database, and schedules a rescan if the catalog is behind.
Connections and write threads:
- A BaseException from a write or isolated callback is delivered to the
caller as a RuntimeError instead of killing the thread silently.
- conn.close() on a write lease raises ConnectionLeaseError, and the write
thread reopens a connection something else closed.
- Write connections pin PRAGMA recursive_triggers=on (sqlite-utils FTS
triggers rely on it; idle reopen lost the old drift).
- execute_fn() accepts generators that no longer hold the connection or a
cursor.
- --crossdb _memory connections count against max_open_connections, are
reaped, and are discarded when databases are added or removed.
Lifecycle:
- The temp internal database file uses weakref.finalize, not atexit, so
closed or abandoned instances can be garbage collected.
- The read-pool reaper no longer keeps the last pool alive in its frame.
- The scratch directory is loaded (and locked) at the end of __init__, so a
failed construction leaves nothing locked.
- config_dir/scratch is used only if empty or created by Datasette; a second
instance on the same config dir starts without it; sidecar files are never
deleted the first time a directory is opened.
Regression tests: tests/test_connection_review_fixes.py (24 of 27 fail on
|
||
|---|---|---|
| .github | ||
| datasette | ||
| demos | ||
| docs | ||
| tests | ||
| .coveragerc | ||
| .dockerignore | ||
| .git-blame-ignore-revs | ||
| .gitattributes | ||
| .gitignore | ||
| .isort.cfg | ||
| .prettierrc | ||
| .readthedocs.yaml | ||
| CODE_OF_CONDUCT.md | ||
| codecov.yml | ||
| Dockerfile | ||
| Justfile | ||
| LICENSE | ||
| MANIFEST.in | ||
| package-lock.json | ||
| package.json | ||
| pyproject.toml | ||
| pytest.ini | ||
| README.md | ||
| ruff.toml | ||
| setup.cfg | ||
| test-in-pyodide-with-shot-scraper.sh | ||





An open source multi-tool for exploring and publishing data
Datasette is a tool for exploring and publishing data. It helps people take data of any shape or size and publish that as an interactive, explorable website and accompanying API.
Datasette is aimed at data journalists, museum curators, archivists, local governments, scientists, researchers and anyone else who has data that they wish to share with the world.
Explore a demo, watch a video about the project or try it out on GitHub Codespaces.
- datasette.io is the official project website
- Latest Datasette News
- Comprehensive documentation: https://docs.datasette.io/
- Examples: https://datasette.io/examples
- Live demo of current
mainbranch: https://latest.datasette.io/ - Questions, feedback or want to talk about the project? Join our Discord
Want to stay up-to-date with the project? Subscribe to the Datasette newsletter for tips, tricks and news on what's new in the Datasette ecosystem.
Installation
If you are on a Mac, Homebrew is the easiest way to install Datasette:
brew install datasette
You can also install it using pip or pipx:
pip install datasette
Datasette requires Python 3.10 or higher. We also have detailed installation instructions covering other options such as Docker.
Basic usage
datasette serve path/to/database.db
This will start a web server on port 8001 - visit http://localhost:8001/ to access the web interface.
serve is the default subcommand, you can omit it if you like.
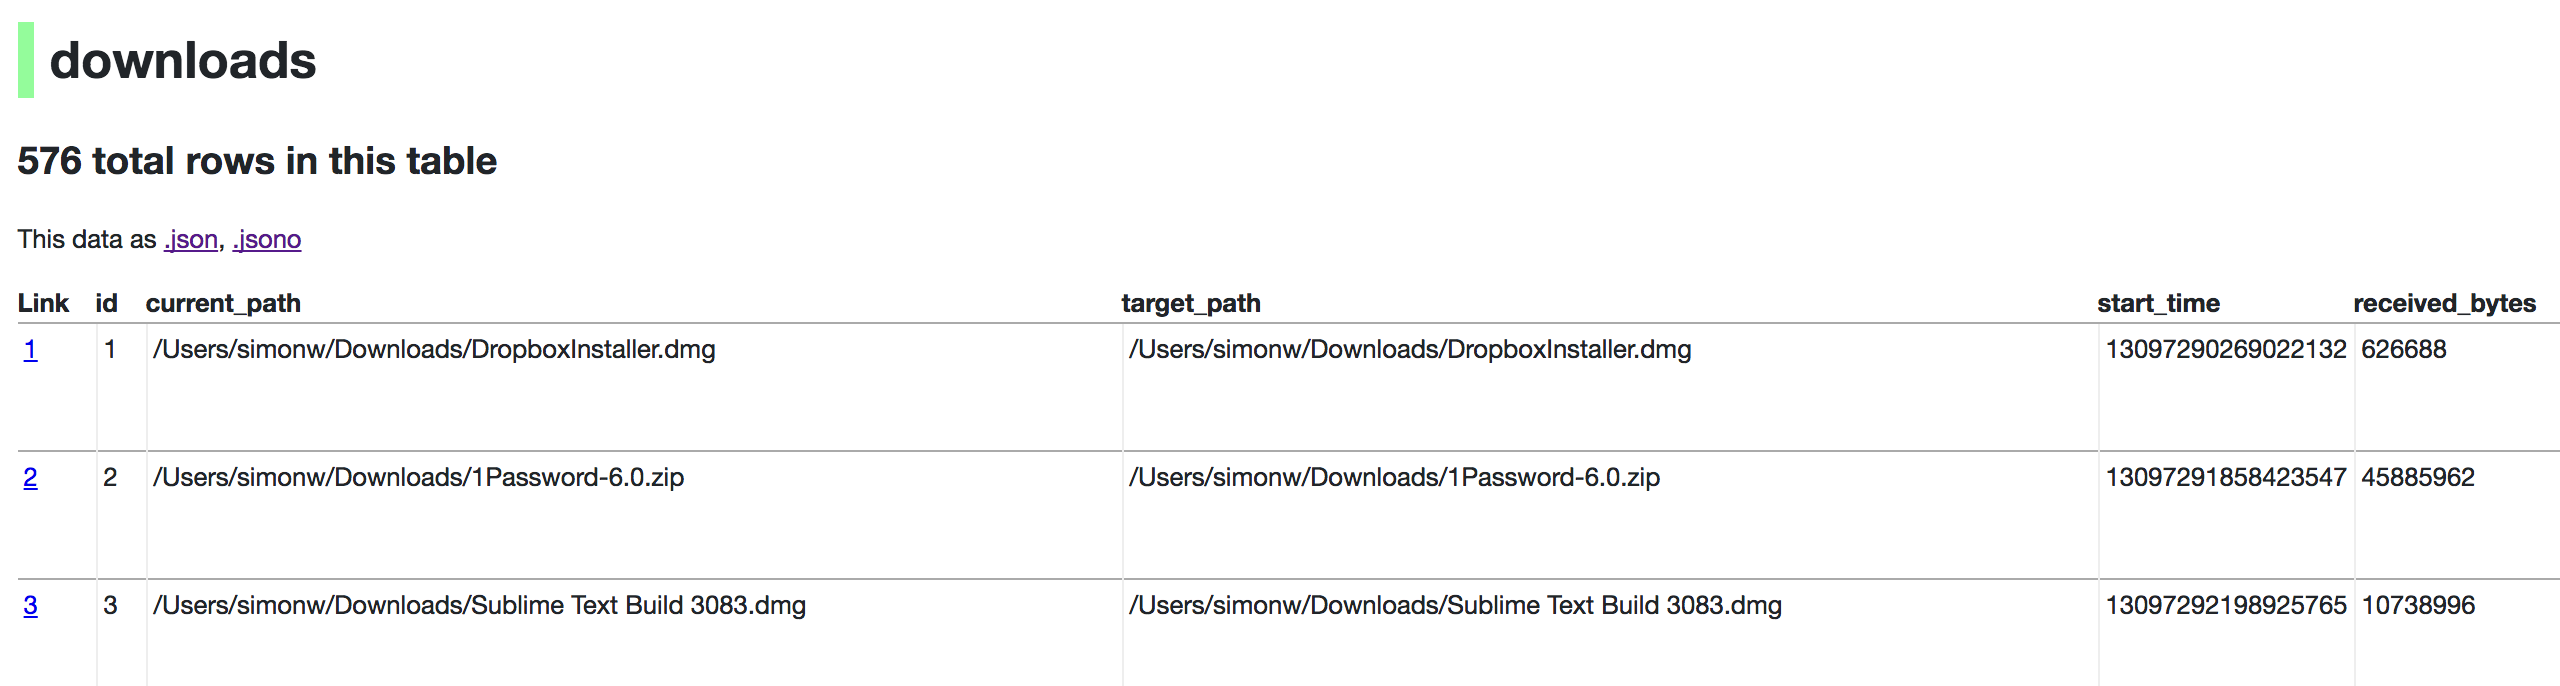
Use Chrome on OS X? You can run datasette against your browser history like so:
datasette ~/Library/Application\ Support/Google/Chrome/Default/History --nolock
Now visiting http://localhost:8001/History/downloads will show you a web interface to browse your downloads data:
metadata.json
If you want to include licensing and source information in the generated datasette website you can do so using a JSON file that looks something like this:
{
    "title": "Five Thirty Eight",
    "license": "CC Attribution 4.0 License",
    "license_url": "http://creativecommons.org/licenses/by/4.0/",
    "source": "fivethirtyeight/data on GitHub",
    "source_url": "https://github.com/fivethirtyeight/data"
}
Save this in metadata.json and run Datasette like so:
datasette serve fivethirtyeight.db -m metadata.json
The license and source information will be displayed on the index page and in the footer. They will also be included in the JSON produced by the API.
datasette publish
If you have Heroku or Google Cloud Run configured, Datasette can deploy one or more SQLite databases to the internet with a single command:
datasette publish heroku database.db
Or:
datasette publish cloudrun database.db
This will create a docker image containing both the datasette application and the specified SQLite database files. It will then deploy that image to Heroku or Cloud Run and give you a URL to access the resulting website and API.
See Publishing data in the documentation for more details.
Datasette Lite
Datasette Lite is Datasette packaged using WebAssembly so that it runs entirely in your browser, no Python web application server required. Read more about that in the Datasette Lite documentation.