- Python 81.9%
- JavaScript 9.8%
- HTML 5.6%
- CSS 2.5%
- Shell 0.1%
 da523c30e5 tests/connection_torture.py drives one Datasette from several event loops (threads) with the smallest pool, 1ms idle timeout and 10ms schema polling through every connection operation, plus add/remove_database, scratch databases, external schema changes, replaced/deleted files, cancellation, Database.close()/Datasette.close() mid-flight and non-threaded mode. One scenario per process, so crashes and hangs are results. It checks for hangs, crashes, undocumented exceptions, per-database write order, lost writes, read-your-writes, catalog freshness, and fds/threads/the instance released after close(). tests/test_connection_torture.py runs a short fixed-seed subset of every scenario. Fixes for what it found: - A cursor that left the thread owning its connection (the cursor returned by execute_write_many()/execute_write_script(), one returned by a write callback, one rejected by execute_fn(), or one held by an exception's frames) could be freed on the event loop thread while the connection ran the same SQL again; on Python < 3.12 freeing it resets the shared cached statement, and the other query failed with "bad parameter or other API misuse". Such cursors are now closed on the owning thread. Pre-existing on main (51 failures per 1,800 multi-loop execute_write_many calls). - invoke_startup() is single-flight across event loops (a concurrent.futures future, datasette.utils.inflight) instead of _startup_sequence() holding an asyncio.Lock: a second loop got "bound to a different event loop" or hung, and two loops could run the startup hooks twice. A request made from a startup hook no longer re-runs or deadlocks startup. - The index page takes one snapshot of ds.databases: a database removed, renamed or closed mid-request, or whose file was deleted, no longer turns the page into a 500. Database.size is 0 for a deleted file. The scan-coalescing helpers move to datasette/utils/inflight.py. Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com> Claude-Session: https://claude.ai/code/session_01EwkLo2rJWidpkDVT3HkvNv |
||
|---|---|---|
| .github | ||
| datasette | ||
| demos | ||
| docs | ||
| tests | ||
| .coveragerc | ||
| .dockerignore | ||
| .git-blame-ignore-revs | ||
| .gitattributes | ||
| .gitignore | ||
| .isort.cfg | ||
| .prettierrc | ||
| .readthedocs.yaml | ||
| CODE_OF_CONDUCT.md | ||
| codecov.yml | ||
| Dockerfile | ||
| Justfile | ||
| LICENSE | ||
| MANIFEST.in | ||
| package-lock.json | ||
| package.json | ||
| pyproject.toml | ||
| pytest.ini | ||
| README.md | ||
| ruff.toml | ||
| setup.cfg | ||
| test-in-pyodide-with-shot-scraper.sh | ||





An open source multi-tool for exploring and publishing data
Datasette is a tool for exploring and publishing data. It helps people take data of any shape or size and publish that as an interactive, explorable website and accompanying API.
Datasette is aimed at data journalists, museum curators, archivists, local governments, scientists, researchers and anyone else who has data that they wish to share with the world.
Explore a demo, watch a video about the project or try it out on GitHub Codespaces.
- datasette.io is the official project website
- Latest Datasette News
- Comprehensive documentation: https://docs.datasette.io/
- Examples: https://datasette.io/examples
- Live demo of current
mainbranch: https://latest.datasette.io/ - Questions, feedback or want to talk about the project? Join our Discord
Want to stay up-to-date with the project? Subscribe to the Datasette newsletter for tips, tricks and news on what's new in the Datasette ecosystem.
Installation
If you are on a Mac, Homebrew is the easiest way to install Datasette:
brew install datasette
You can also install it using pip or pipx:
pip install datasette
Datasette requires Python 3.10 or higher. We also have detailed installation instructions covering other options such as Docker.
Basic usage
datasette serve path/to/database.db
This will start a web server on port 8001 - visit http://localhost:8001/ to access the web interface.
serve is the default subcommand, you can omit it if you like.
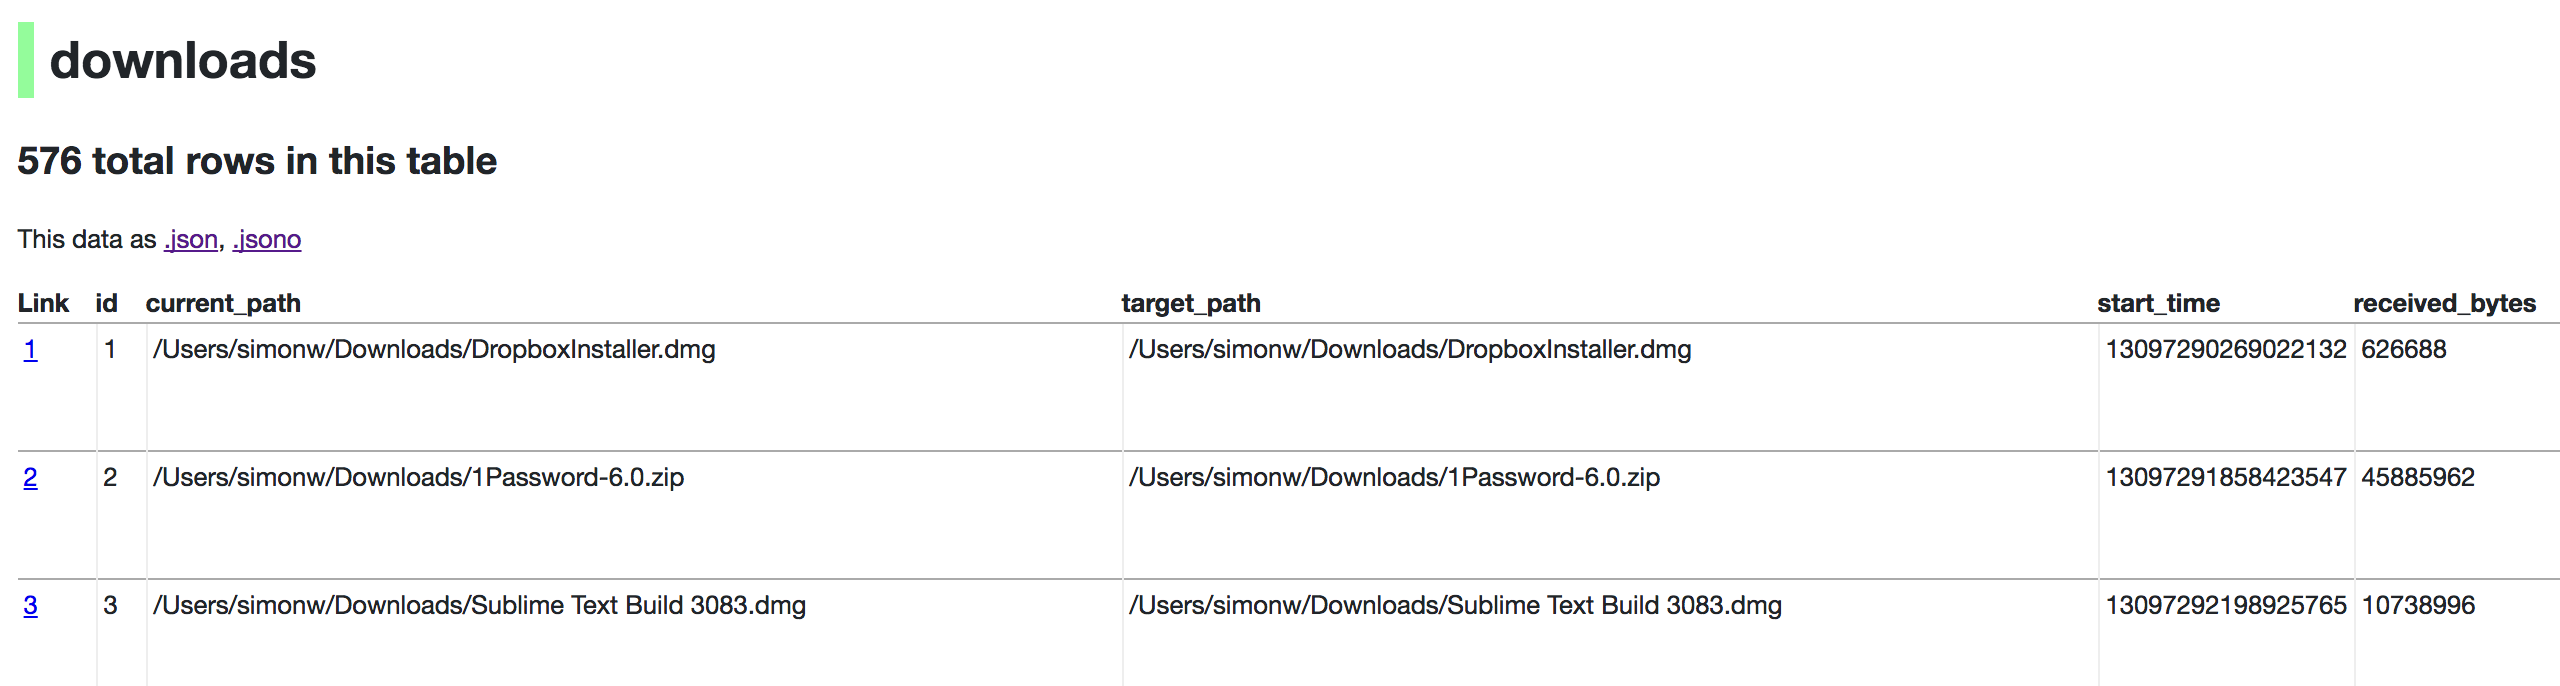
Use Chrome on OS X? You can run datasette against your browser history like so:
datasette ~/Library/Application\ Support/Google/Chrome/Default/History --nolock
Now visiting http://localhost:8001/History/downloads will show you a web interface to browse your downloads data:
metadata.json
If you want to include licensing and source information in the generated datasette website you can do so using a JSON file that looks something like this:
{
    "title": "Five Thirty Eight",
    "license": "CC Attribution 4.0 License",
    "license_url": "http://creativecommons.org/licenses/by/4.0/",
    "source": "fivethirtyeight/data on GitHub",
    "source_url": "https://github.com/fivethirtyeight/data"
}
Save this in metadata.json and run Datasette like so:
datasette serve fivethirtyeight.db -m metadata.json
The license and source information will be displayed on the index page and in the footer. They will also be included in the JSON produced by the API.
datasette publish
If you have Heroku or Google Cloud Run configured, Datasette can deploy one or more SQLite databases to the internet with a single command:
datasette publish heroku database.db
Or:
datasette publish cloudrun database.db
This will create a docker image containing both the datasette application and the specified SQLite database files. It will then deploy that image to Heroku or Cloud Run and give you a URL to access the resulting website and API.
See Publishing data in the documentation for more details.
Datasette Lite
Datasette Lite is Datasette packaged using WebAssembly so that it runs entirely in your browser, no Python web application server required. Read more about that in the Datasette Lite documentation.